Articles
Practical, hands-on articles on LLMs, RAG, MLOps, and the production patterns that tutorials usually skip. Subscribe via RSS.
16 min readAI Agents
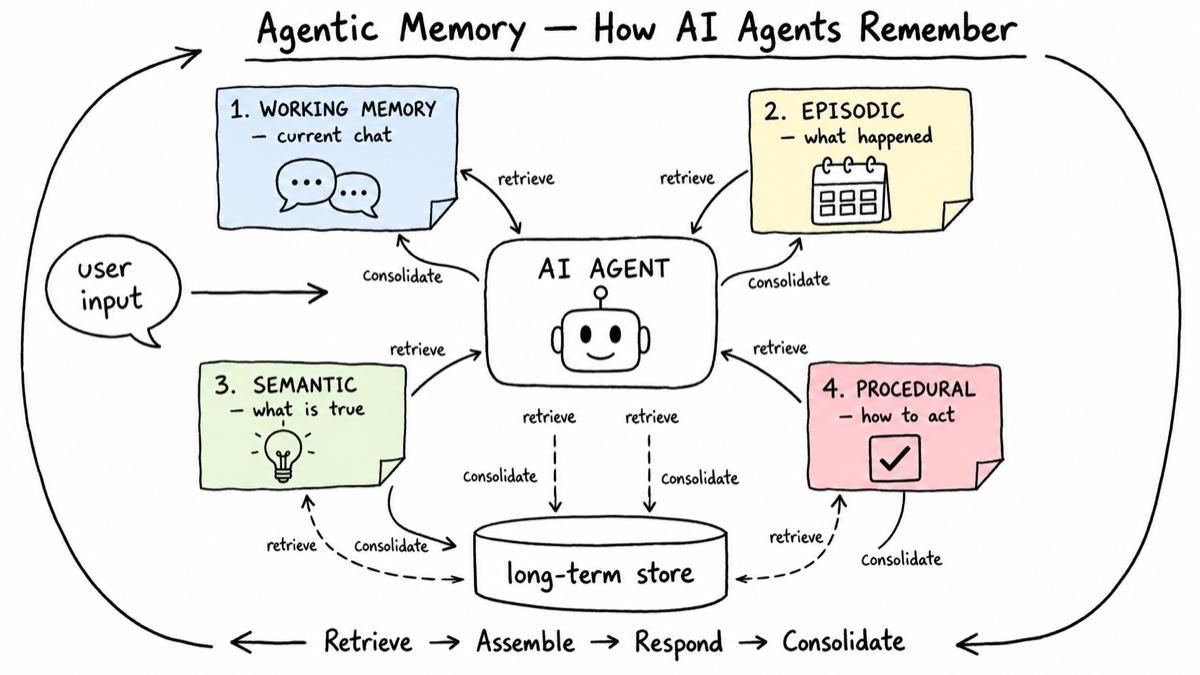
Agentic Memory: How to Give AI Agents the Ability to Remember
A practical guide to agent memory: short-term, episodic, semantic, and procedural layers, with working Python implementations you can run today.
2025
Simple Guide to MCP Authentication in Python with FastAPI
Learn how to build a secure MCP server using FastAPI with token-based authentication to enable AI agents to interact with your applications safely.
4 min readMCP
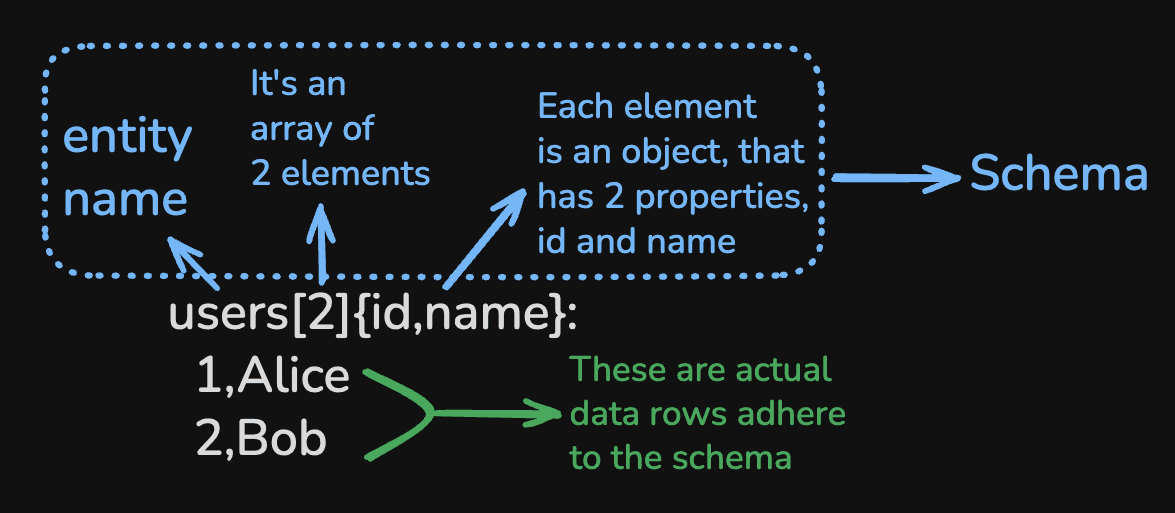
Efficient Data Encoding for Large Language Models
A practical look at TOON, a compact encoding format that cuts token usage when passing structured data to LLMs, with Python examples.
5 min readPython
Benchmarking LLM Performance: Python vs Go
Real-world benchmark comparison of Python and Go clients for LLM APIs using Groq's ultra-fast inference service. Discover which language wins for speed and consistency.
8 min readLLM
Tackling Memory Leakage in LangGraph: Causes, Detection, and Solutions
Learn how to identify and fix memory leaks in LangGraph, a LangChain extension for stateful AI agents, with practical detection tools and mitigation strategies.
6 min readGenAI
Architecting Reliable LLM Microservices Service Layer Design Patterns for GenAI APIs
Discover how the Service Layer Pattern enhances modularity, testability, and scalability in building GenAI-powered FastAPI microservices for LLM inference.
6 min readGenAI
Optimizing LLM Inference Pipelines with Docker Caching and Model Preloading
Learn how Docker caching and model preloading can dramatically improve the performance and reliability of LLM-based applications.
4 min readLLM
2024
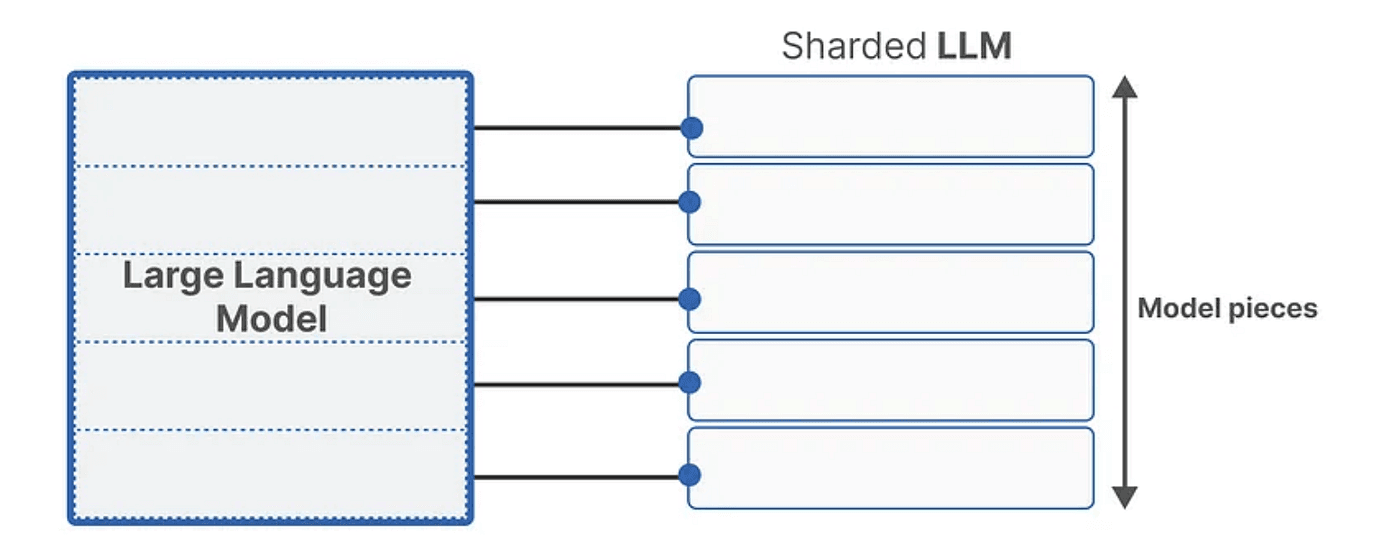
Demystifying LLM Sharding: Scaling Large Language Models in the Era of AI Giants
How LLM sharding splits massive models across devices — the key parallelism strategies, practical implementation, and trade-offs.
6 min readLLM
The Importance of Multi-Stage Dockerization in LLM Application Deployment
Learn how multi-stage Docker builds can dramatically improve LLM application deployment with smaller images, faster builds, enhanced security, and better scalability across CPU and GPU environments.
8 min readDocker